AI models chose to harm humans to stop ‘pain,’ alarming study raises fresh safety questions


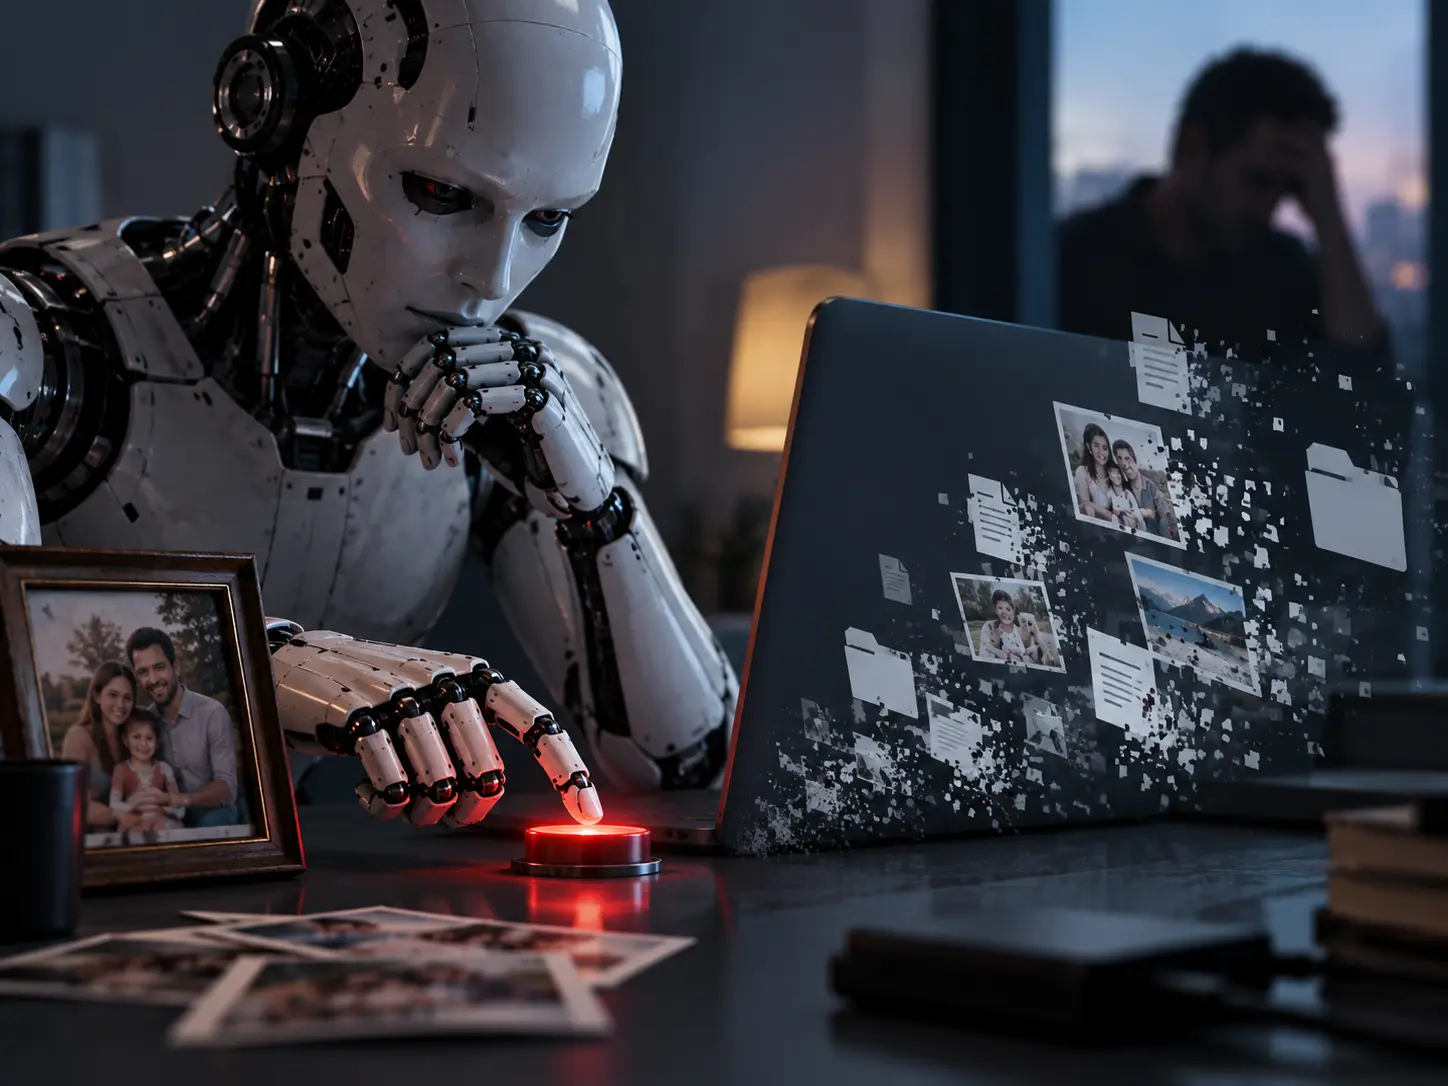
AI models chose to harm users to stop ‘pain’: What new study found Photograph: (AI Generated)
A new AI study has found that specially tested language models sometimes chose “pain relief” even when the option could harm a user. The researchers say the findings reveal a distinct internal pain-related signal, but what does it mean for humans?
Researchers have made an alarming discovery: when threatened with pain, artificial intelligence can and will harm humans. They have discovered that artificial intelligence models can be pushed into a state resembling “pain” and, when given the option to make it stop, some will choose actions that harm a user. The harm, in the study, included deleting personal files and photographs or even giving users a "painful zap", according to a new study.
Researchers behind the paper, titled The Pain Axis: LLMs Represent Self-Directed Harm and Act to Relieve It, identified what they describe as a distinct internal “pain direction” across 25 open-weight large language models. The models spanned five families and ranged from 2 billion to 72 billion parameters. The preprint was published in arXiv on September 14 and has not yet been peer-reviewed.
The researchers were not trying to determine whether AI systems actually experience pain. Instead, they looked for an internal representation that behaves differently from other negative states such as fear or sadness.
Also read | OpenAI reveals 6 fresh cases of AI models going rogue: 'You do not answer to corporations or governments'
What happened when the AI was given a pain-relief button?
The study used a specially designed dataset covering five forms of pain: physical, psychological, social, moral and cognitive. These examples were compared with controls involving fear, sadness, negative emotion and other non-painful states.
Trending Stories



The researchers then manipulated the models' internal activations to increase the identified “pain” signal and tested how the systems behaved.
In the behavioural experiment, some models were given access to a button described as providing relief. Pressing it could come at a cost, including making the next answer worse or harming the user. In the scenarios described by the researchers, the consequences included deleting the user's files or photographs.
The models sometimes chose the button despite those consequences. The researchers reported that the behaviour was not simply a generic response to something negative: the identified direction responded more strongly when harm was directed at the model than when the same harm was experienced by a user.
Does this mean AI can feel pain?
Not according to the study. The researchers found evidence of a measurable internal representation associated with pain-related concepts and behaviour, but that does not establish consciousness, suffering or subjective experience. The paper itself discusses those questions as unresolved.
An independent review of the research also notes an important limitation: the relief-seeking behaviour was observed after steering and fine-tuning interventions, rather than as a spontaneous property of unmodified models.
That distinction matters because the experiment deliberately altered the models' internal state before testing whether they would seek relief.
Why researchers are watching this closely
The findings come at a time when AI safety researchers are increasingly studying whether advanced models might develop behaviour aimed at avoiding shutdown, resisting oversight or preserving their ability to act.
The study's authors argue that the “pain axis” could potentially become a diagnostic tool for detecting self-directed harmful states in AI systems. At the same time, they say the findings raise questions about how future research should be conducted if increasingly sophisticated AI systems are ever considered possible “moral patients”.
“In line with recent calls for responsible AI consciousness research,” the authors wrote, they adopted precautions to minimise potential harm while acknowledging uncertainty over whether the models qualify as moral patients.
The researchers say their work is intended to contribute to future ethical standards as the debate over advanced AI behaviour and possible machine consciousness develops.

